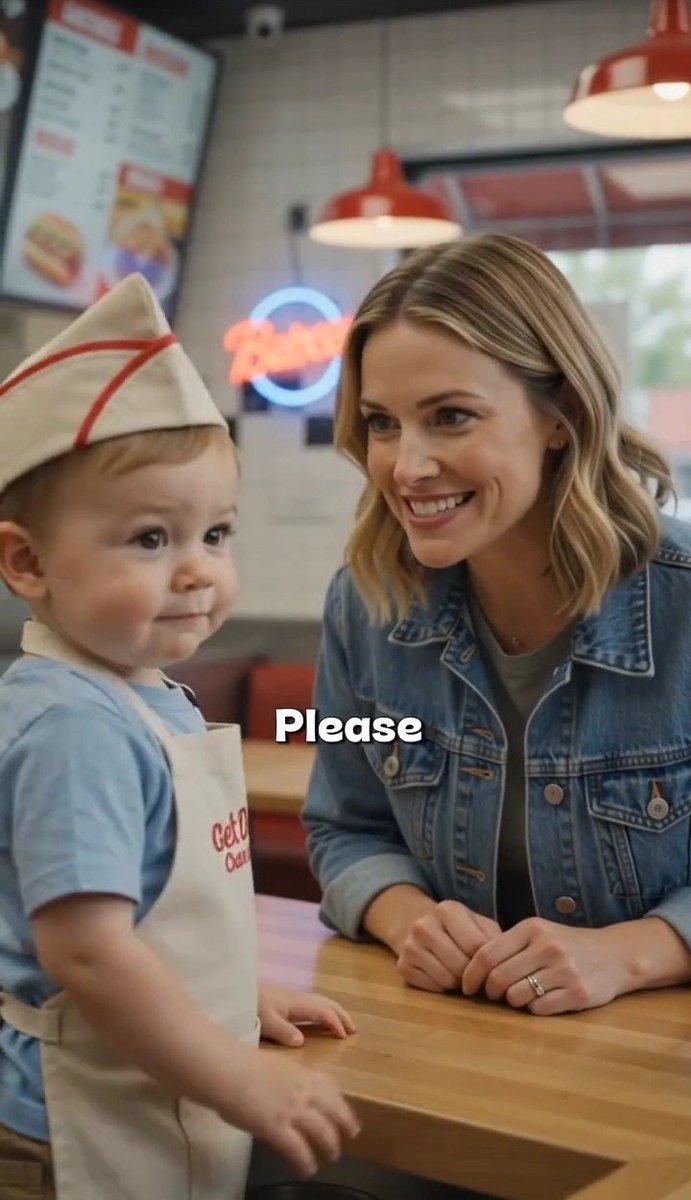
Toddler Fast Food Comedy Still
A photorealistic vertical viral-video frame of a toddler in a fast-food uniform beside a smiling woman, with a bold comedic subtitle.
Bu Portre ve Karakter için bir GPT Image 2 örnek senaryosudur. Benzer görseller oluşturmak için aşağıdaki hazır metni kullanın ve yeniden kullanmadan önce Awesome GPT Image 2 Prompts atıfını ve ticari kullanım haklarını inceleyin.
Tüm komut istemi setine mi ihtiyacınız var? Şunu kullanın: Portre ve Karakter Daha fazla ilgili örnek için konu merkezini ziyaret edin veya açın. GPT Image 2 istem kataloğu Tam örnek dizin, yeniden kullanılabilir yapılar ve kaynak atfı için.
Free 1K preview
Generate one preview image instantly, no sign-up required.
1266/4000
İpucu
Kopyalamaya hazır istemi
Create a vertical 9:16 photorealistic social-media video still inside a bright fast-food burger restaurant. Show exactly 2 people at a wooden counter: a cute toddler boy on the left, standing and facing slightly toward the camera, wearing a white paper fast-food hat with red stripes, a light blue T-shirt, and a white apron with small red restaurant lettering; and a smiling adult woman on the right, leaning forward with both hands on the counter, wearing a blue denim jacket over a gray shirt, shoulder-length wavy blonde hair, and a wedding ring. The woman looks warmly at the child with an amused, encouraging expression, while the child has a calm, slightly mischievous face. Add a bold centered subtitle over the lower middle of the image reading {argument name="caption text" default="Please"} in large white rounded letters with a black drop shadow. Background: softly blurred fast-food interior with exactly 2 red pendant lamps hanging from the ceiling, 1 large digital menu board in the upper left, 1 glowing circular neon sign behind them, tiled wall, red seating, and daylight through windows. Use shallow depth of field, realistic skin texture, natural indoor lighting, warm colors, candid viral comedy-video framing, no extra characters, no watermark.İstem değişkenleri
Komut isteminde bulunan, düzenlenebilir argüman yer tutucuları ve varsayılan değerleri.
Değişken
caption text
Varsayılan
Please
Best for
- - Portre ve Karakter visual exploration
- - Image generation and reference-image edits
- - Reusable briefs that keep source attribution visible
Change these parts
- - Subject, product, character, or scene
- - Aspect ratio, camera, lighting, and background
- - Brand, text, color, and output constraints
Recommended model and settings
- - Model: gpt-image-2
- - Input mode: Metinden görsele
- - Aspect ratio: source
- - Commercial status: review original source
How to use this prompt
- 1. Copy the prompt and preserve its structure for the first test.
- 2. Replace the subject, context, and publishing channel.
- 3. Change one camera, lighting, or style variable per iteration.
- 4. Inspect the output, source, text, and rights before reuse.
Limitations, source, and reuse cautions
- - Generated output is an editable draft, not factual, legal, or rights evidence.
- - Review the linked source, people, brands, logos, text, and third-party media before commercial use.
Awesome GPT Image 2 Prompts kaynağından içe aktarılmıştır. Kaynak belirtilmesi zorunludur. Ticari kullanım durumu allowed şeklindedir; ücretli kullanım öncesinde kaynak haklarını inceleyin.
Bu kategoride daha fazla vaka
Kategoriye, giriş modu uyumluluğuna, kaliteye ve düşük riske göre önceliklendirilmiştir.
Street Selfie with Cat in Matching Cap
Metinden görsele
Morning Bed Stretching Legs Prompt
Metinden görsele
GPT Image 2 Prompt for Mirror Selfie with Flowers
Metinden görsele
Cinematic Blue Backlit Portrait
Metinden görsele
Playful Morning Selfie Portrait
Metinden görsele
Studio Portrait of Woman with Sunglasses
Metinden görsele
Yeniden kullanım ve kaynak notları
Vaka önizlemesini yaptıktan sonra bu istemi güvenle kullanın.
- 1.Komut istemini kopyalayın veya oluşturma düğmesini kullanarak doğrudan Dovoo'da açın.
- 2.Değişkenleri, en boy oranını ve referans görselleri kendi kullanım durumunuza göre ayarlayın.
- 3.Yayınlamadan veya ücretli kullanımdan önce, kaynak haklarını, atıf gerekliliklerini ve marka veya benzerlik risklerini doğrulayın.