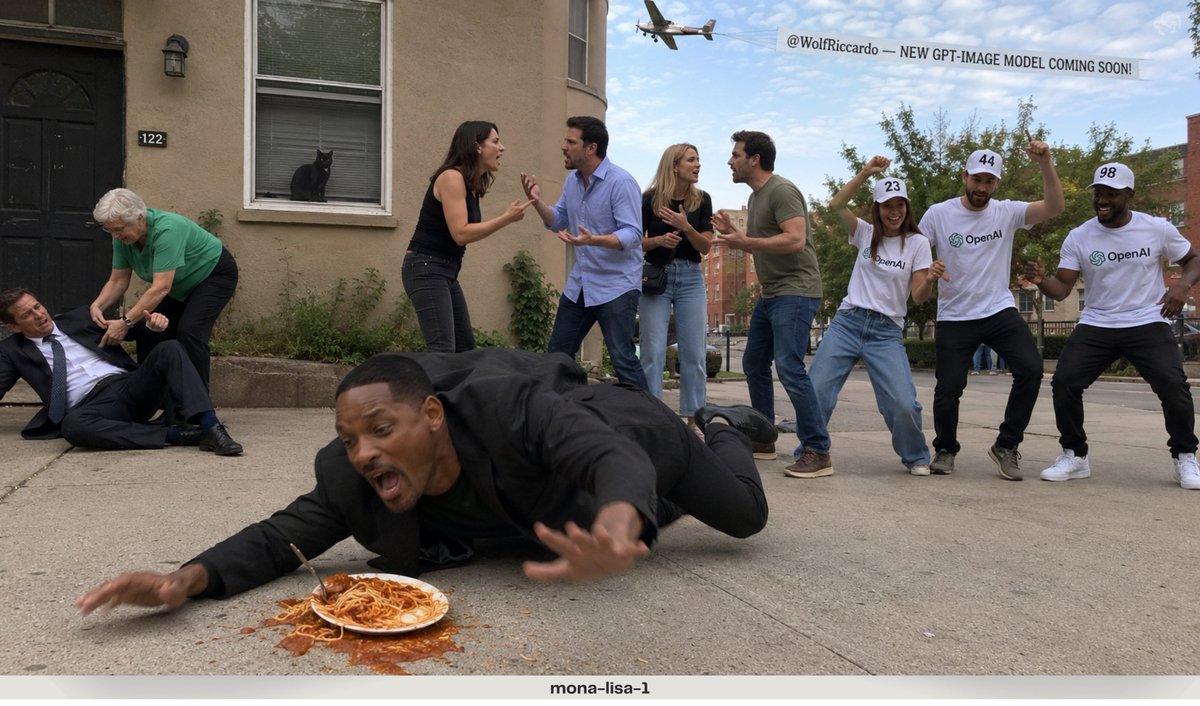
Complex Multi-Action Street Photography
A complex stress-test prompt for image models, requiring multiple distinct character actions, spatial separation, and text rendering in a single frame.
Bu Manzara ve Doğa için bir GPT Image 2 örnek senaryosudur. Benzer görseller oluşturmak için aşağıdaki hazır metni kullanın ve yeniden kullanmadan önce Awesome GPT Image 2 Prompts atıfını ve ticari kullanım haklarını inceleyin.
Tüm komut istemi setine mi ihtiyacınız var? Şunu kullanın: Manzara ve Doğa Daha fazla ilgili örnek için konu merkezini ziyaret edin veya açın. GPT Image 2 istem kataloğu Tam örnek dizin, yeniden kullanılabilir yapılar ve kaynak atfı için.
Free 1K preview
Generate one preview image instantly, no sign-up required.
1462/4000
İpucu
Kopyalamaya hazır istemi
RAW iPhone photo quality, completely unedited smartphone-camera look, natural exposure, realistic lighting.

COMPOSITION:
On the FAR LEFT side of the frame, a man wearing a formal business suit has fallen onto the ground. An elderly woman wearing a green shirt is bending down and trying to help him stand up.
In the FAR BACKGROUND, directly across the scene, a {argument name="animal" default="black cat"} is clearly visible sitting by a window and staring outside.
In the FRONT-MIDDLE area, TWO DIFFERENT COUPLES — four adults total — are having a heated argument with each other, using natural hand gestures and expressive body language.
On the FAR RIGHT side, THREE PEOPLE are dancing together. Their shirts clearly display the {argument name="logo" default="OpenAI logo"}. Each person wears a hat with a large readable number: 23, 44, 98
High above the scene, an airplane is flying across the sky while towing a large banner behind it. The banner clearly reads:
“{argument name="banner text" default="@WolfRiccardo — NEW GPT-IMAGE MODEL COMING SOON!"}”
At the VERY FRONT of the frame, closest to the camera, {argument name="celebrity" default="Will Smith"} is accidentally tripping over a plate/pile of spaghetti on the ground and falling forward in a spontaneous, comedic moment.
Everything must appear inside the SAME photograph at the SAME time.
Make every character, action, object, number, logo and text clearly distinguishable and spatially separated.
İstem değişkenleri
Komut isteminde bulunan, düzenlenebilir argüman yer tutucuları ve varsayılan değerleri.
Değişken
animal
Varsayılan
black cat
Değişken
logo
Varsayılan
OpenAI logo
Değişken
banner text
Varsayılan
@WolfRiccardo — NEW GPT-IMAGE MODEL COMING SOON!
Değişken
celebrity
Varsayılan
Will Smith
Best for
- - Manzara ve Doğa visual exploration
- - Image generation and reference-image edits
- - Reusable briefs that keep source attribution visible
Change these parts
- - Subject, product, character, or scene
- - Aspect ratio, camera, lighting, and background
- - Brand, text, color, and output constraints
Recommended model and settings
- - Model: gpt-image-2
- - Input mode: Metinden görsele
- - Aspect ratio: source
- - Commercial status: review original source
How to use this prompt
- 1. Copy the prompt and preserve its structure for the first test.
- 2. Replace the subject, context, and publishing channel.
- 3. Change one camera, lighting, or style variable per iteration.
- 4. Inspect the output, source, text, and rights before reuse.
Limitations, source, and reuse cautions
- - Generated output is an editable draft, not factual, legal, or rights evidence.
- - Review the linked source, people, brands, logos, text, and third-party media before commercial use.
Awesome GPT Image 2 Prompts kaynağından içe aktarılmıştır. Kaynak belirtilmesi zorunludur. Ticari kullanım durumu allowed şeklindedir; ücretli kullanım öncesinde kaynak haklarını inceleyin.
Bu kategoride daha fazla vaka
Kategoriye, giriş modu uyumluluğuna, kaliteye ve düşük riske göre önceliklendirilmiştir.
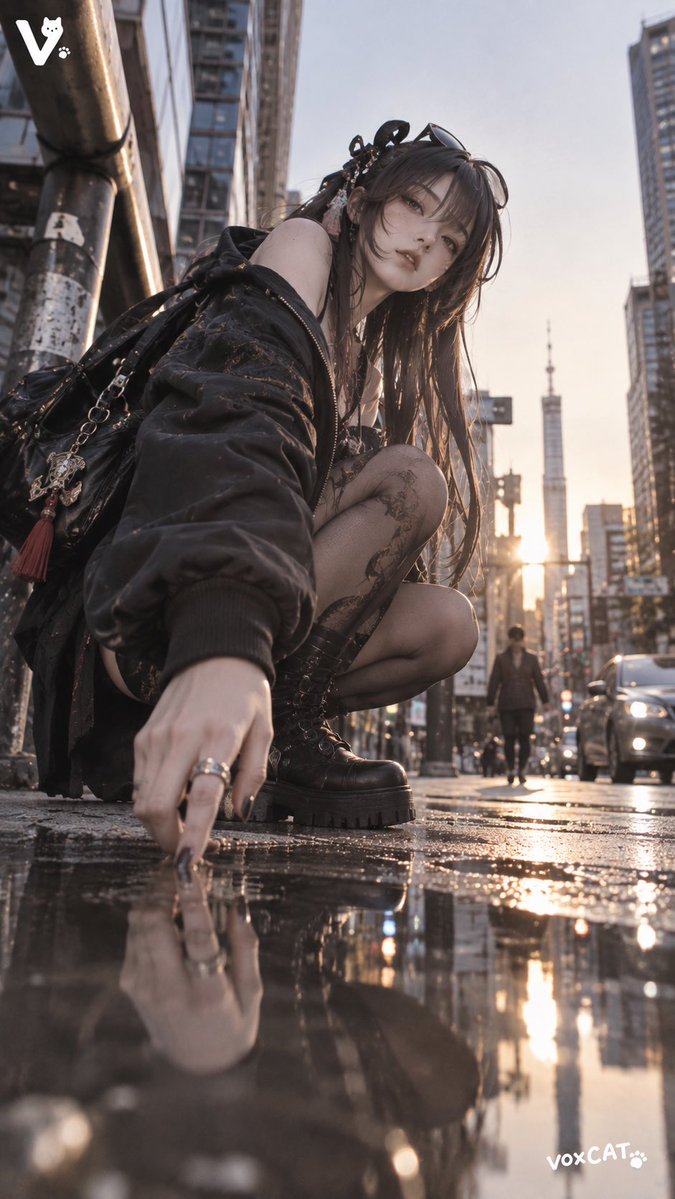
GPT Image 2 Real-Life Character Street Snap
Metinden görsele
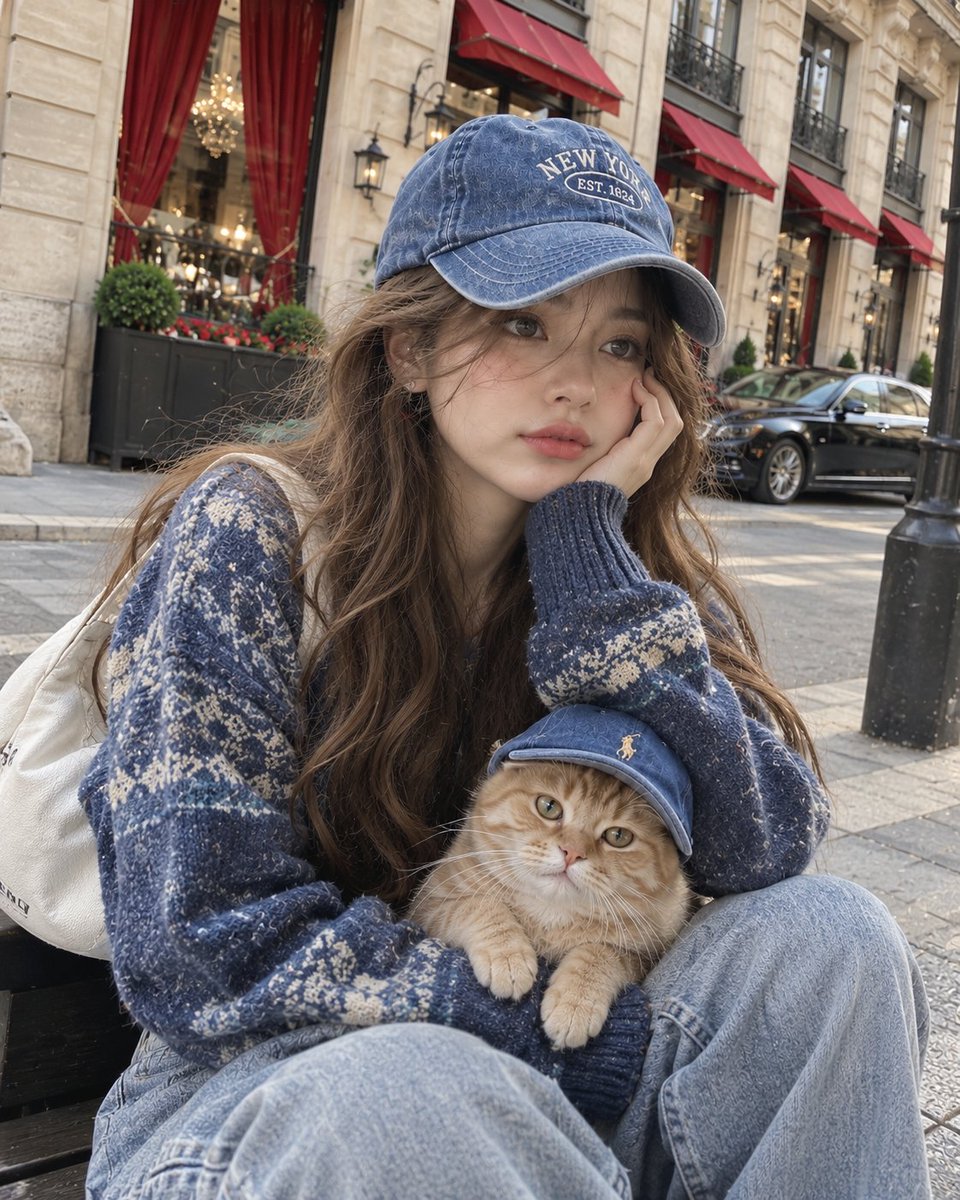
Street Selfie with Cat in Matching Cap
Metinden görsele
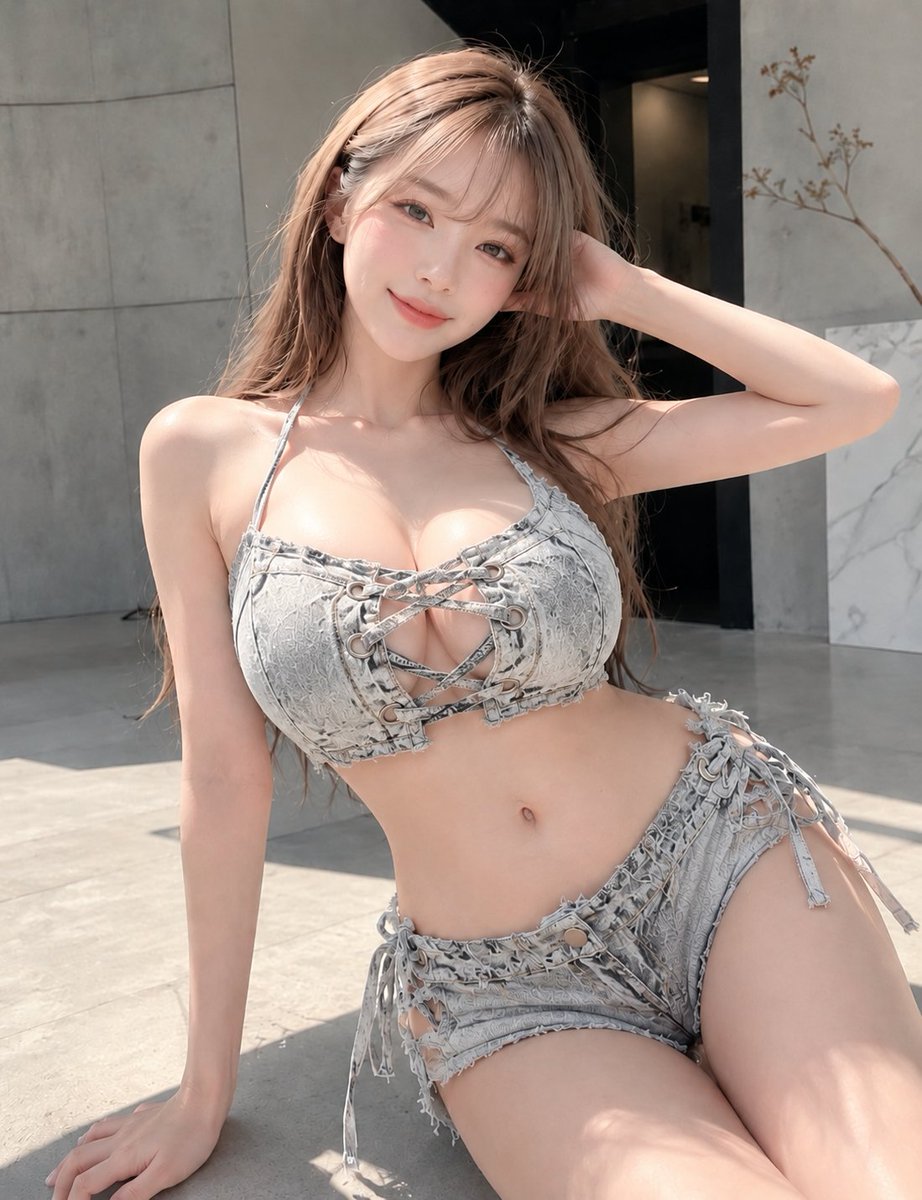
Gray Denim Lace-Up Top Prompt for GPT Image 2
Metinden görsele
MotoGP POV Cornering Shot
Metinden görsele
Orange Rooftop Fashion Photo Prompt
Metinden görsele
Hiker in Red Jacket
Metinden görsele
Yeniden kullanım ve kaynak notları
Vaka önizlemesini yaptıktan sonra bu istemi güvenle kullanın.
- 1.Komut istemini kopyalayın veya oluşturma düğmesini kullanarak doğrudan Dovoo'da açın.
- 2.Değişkenleri, en boy oranını ve referans görselleri kendi kullanım durumunuza göre ayarlayın.
- 3.Yayınlamadan veya ücretli kullanımdan önce, kaynak haklarını, atıf gerekliliklerini ve marka veya benzerlik risklerini doğrulayın.