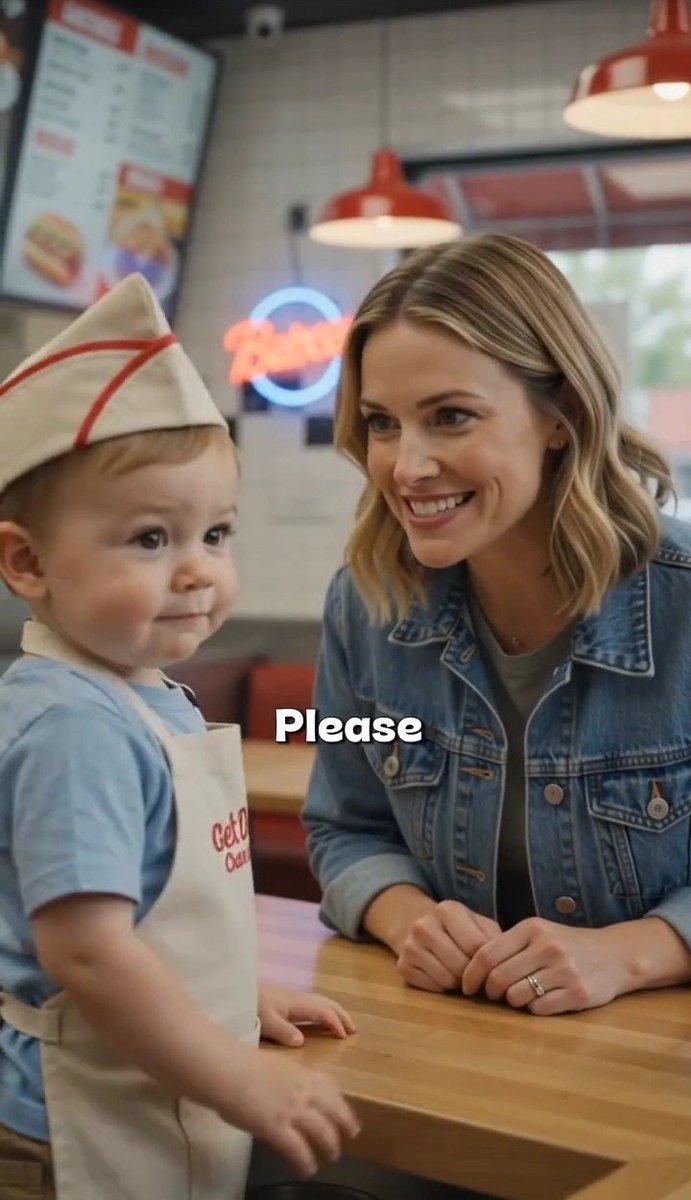
Toddler Fast Food Comedy Still
A photorealistic vertical viral-video frame of a toddler in a fast-food uniform beside a smiling woman, with a bold comedic subtitle.
Questo è un esempio di prompt GPT Image 2 per Ritratto e personaggio . Utilizza il prompt pronto per la copia qui sotto per generare immagini simili e verifica l'attribuzione Awesome GPT Image 2 Prompts e i diritti di utilizzo commerciale prima del riutilizzo.
Hai bisogno del set completo di prompt? Usa il Ritratto e personaggio hub tematico per ulteriori esempi correlati oppure apri il GPT Image 2 catalogo rapido per l'indice completo degli esempi, le strutture riutilizzabili e l'attribuzione delle fonti.
Free 1K preview
Generate one preview image instantly, no sign-up required.
1266/4000
Richiesta
prompt pronto per la copia
Create a vertical 9:16 photorealistic social-media video still inside a bright fast-food burger restaurant. Show exactly 2 people at a wooden counter: a cute toddler boy on the left, standing and facing slightly toward the camera, wearing a white paper fast-food hat with red stripes, a light blue T-shirt, and a white apron with small red restaurant lettering; and a smiling adult woman on the right, leaning forward with both hands on the counter, wearing a blue denim jacket over a gray shirt, shoulder-length wavy blonde hair, and a wedding ring. The woman looks warmly at the child with an amused, encouraging expression, while the child has a calm, slightly mischievous face. Add a bold centered subtitle over the lower middle of the image reading {argument name="caption text" default="Please"} in large white rounded letters with a black drop shadow. Background: softly blurred fast-food interior with exactly 2 red pendant lamps hanging from the ceiling, 1 large digital menu board in the upper left, 1 glowing circular neon sign behind them, tiled wall, red seating, and daylight through windows. Use shallow depth of field, realistic skin texture, natural indoor lighting, warm colors, candid viral comedy-video framing, no extra characters, no watermark.Variabili di richiesta
Segnaposto per gli argomenti modificabili presenti nel prompt, con i relativi valori predefiniti.
Variabile
caption text
Predefinito
Please
Best for
- - Ritratto e personaggio visual exploration
- - Image generation and reference-image edits
- - Reusable briefs that keep source attribution visible
Change these parts
- - Subject, product, character, or scene
- - Aspect ratio, camera, lighting, and background
- - Brand, text, color, and output constraints
Recommended model and settings
- - Model: gpt-image-2
- - Input mode: Testo in immagine
- - Aspect ratio: source
- - Commercial status: review original source
How to use this prompt
- 1. Copy the prompt and preserve its structure for the first test.
- 2. Replace the subject, context, and publishing channel.
- 3. Change one camera, lighting, or style variable per iteration.
- 4. Inspect the output, source, text, and rights before reuse.
Limitations, source, and reuse cautions
- - Generated output is an editable draft, not factual, legal, or rights evidence.
- - Review the linked source, people, brands, logos, text, and third-party media before commercial use.
Importato da Awesome GPT Image 2 Prompts . È richiesta l'attribuzione. Lo stato di utilizzo commerciale è allowed ; verificare i diritti della fonte prima dell'utilizzo a pagamento.
Altri casi in questa categoria
Prioritizzazione in base a categoria, compatibilità della modalità di input, qualità e minor rischio.
Street Selfie with Cat in Matching Cap
Testo in immagine
Morning Bed Stretching Legs Prompt
Testo in immagine
GPT Image 2 Prompt for Mirror Selfie with Flowers
Testo in immagine
Cinematic Blue Backlit Portrait
Testo in immagine
Playful Morning Selfie Portrait
Testo in immagine
Studio Portrait of Woman with Sunglasses
Testo in immagine
Note sul riutilizzo e sulla fonte
Utilizza questo prompt in tutta sicurezza dopo aver visualizzato in anteprima il caso.
- 1.Copia il prompt oppure aprilo direttamente in Dovoo tramite il pulsante di generazione.
- 2.Regola le variabili, le proporzioni e le immagini di riferimento in base alle tue esigenze.
- 3.Prima della pubblicazione o dell'utilizzo a pagamento, verificare i diritti di fonte, i requisiti di attribuzione e i rischi relativi al marchio o all'immagine.